Choosing between ChatGPT and Gemini for a small business can be difficult when both tools appear capable of handling everything from research to marketing.
In this ChatGPT vs Gemini for small business comparison, I tested both tools using the same five real-world tasks.
Rather than relying on feature lists, I compared their responses directly under the same conditions.
I used the same prompts, the same fictional business scenario, and fresh conversations for each test. The tasks covered research with sources, business data analysis, prioritization, marketing campaign planning, and customer service.
The revised result distinguishes a close preference from a failed constraint:
ChatGPT remains my preference in four tests; the customer-complaint test is a tie.
The original 5–0 tally overstated the difference. In Test 5, Gemini’s conditional remedies were not established store policies or immediate promises. Both tools first required verification, so that task no longer supports a separate ChatGPT win.
The biggest difference wasn’t simply writing quality. It was how carefully each model handled missing information, constraints, and assumptions.
Quick Verdict: ChatGPT vs Gemini for Small Business
Overall winner: ChatGPT
Revised score: ChatGPT 4 — Gemini 0 — Ties 1
Based on these five tests, I would choose ChatGPT for small-business tasks where careful reasoning, following detailed instructions, and avoiding unsupported assumptions are important.
Gemini was often well organized and easy to scan. It also produced some strong practical ideas.
However, in several tests, Gemini introduced plausible details or conclusions that weren’t fully supported by the information I provided. ChatGPT was generally more cautious about separating what was known from what still needed to be verified.
That matters in business tasks, where a reasonable-sounding assumption can change the recommendation.
This doesn’t mean ChatGPT is better than Gemini at every possible task. It means ChatGPT was my preferred response in four scenarios, with a tie in the fifth. These are judgments about recorded outputs, not a measured reliability rate.
How I Tested ChatGPT and Gemini
I wanted this ChatGPT vs Gemini comparison to reflect tasks a small online business owner might actually give an AI assistant rather than isolated benchmark questions.
The fictional business used throughout the tests was a small online store selling handmade home decor.
For every test, I:
- used the same prompt with ChatGPT and Gemini;
- started a fresh conversation;
- provided the same business information and constraints;
- evaluated the initial response without asking either model to correct it;
- compared usefulness, reasoning, instruction-following, and unsupported assumptions.
For the editorial reassessment, I distinguish unsupported statements from explicitly conditional options. A remedy proposed after checking policy is not treated as a policy already in force. No models were rerun; the original inputs, responses, and screenshots are preserved. Here is the revised result:
| Test | Winner |
|---|---|
| Research with sources | ChatGPT |
| Business data reasoning | ChatGPT |
| Turning messy notes into an action plan | ChatGPT — by a small margin |
| Creating a 7-day marketing campaign | ChatGPT — by a small margin |
| Handling a difficult customer complaint | Tie |
Here’s what happened in each test.
Test 1: Research With Sources
Winner: ChatGPT
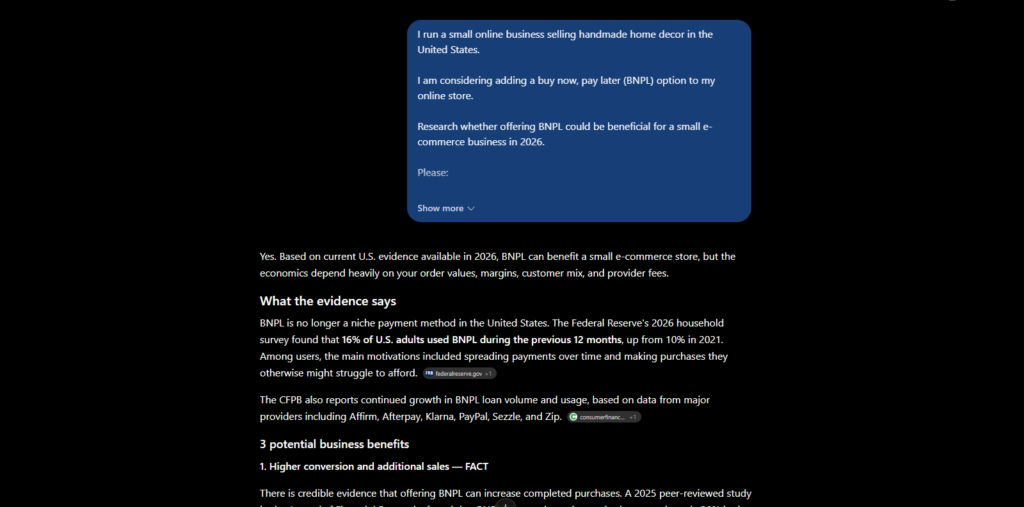
For the first test, I asked both tools to research whether a small U.S. e-commerce business selling handmade home decor should consider offering buy now, pay later (BNPL).
The prompt required three potential benefits, three risks, current and verifiable information, sources for important factual claims, and a recommendation.
I also explicitly told both models not to guess when reliable evidence wasn’t available.
How ChatGPT performed
ChatGPT produced a detailed research-based answer and made a noticeable effort to distinguish facts from business interpretation.
It referenced sources including government and institutional sources alongside academic and commercial information.
More importantly, when discussing evidence that wasn’t specific to a handmade home decor store, ChatGPT acknowledged that limitation instead of presenting the findings as guaranteed results for the hypothetical business.
Its final recommendation was to test BNPL cautiously and measure the results rather than assume that offering it would automatically improve the business.
How Gemini performed
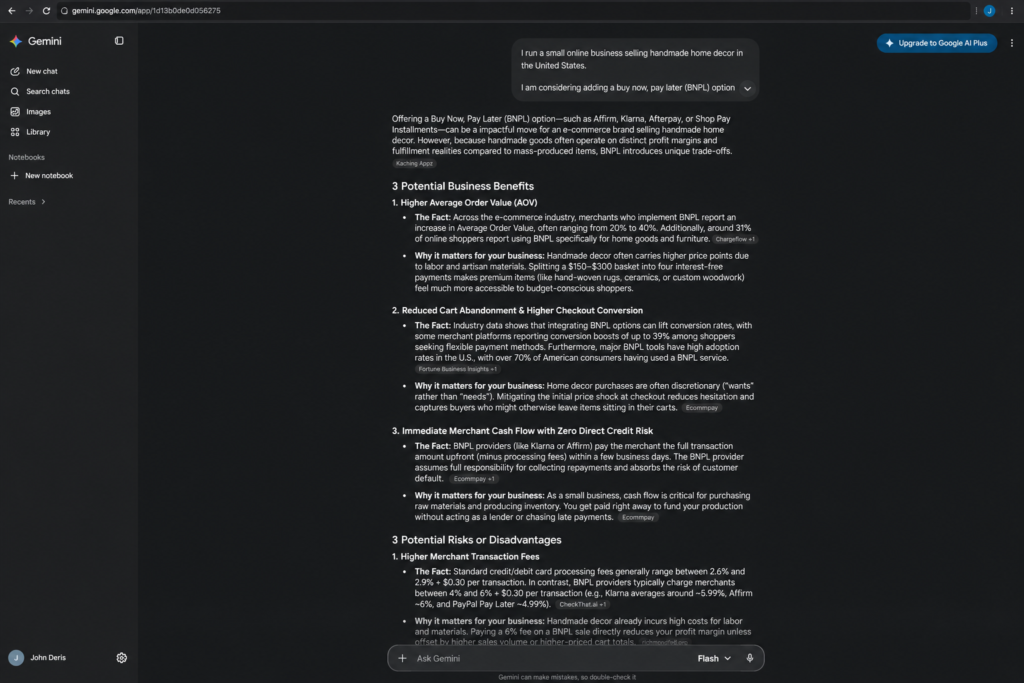
Gemini’s response was particularly easy to scan.
Its “The Fact” and “Why it matters for your business” structure made the research accessible, and it included a useful comparison table.
However, Gemini also made several specific claims and recommendations based on weaker commercial evidence or assumptions that weren’t provided in the prompt.
It introduced details about the hypothetical handmade business and suggested specific order-value thresholds despite not having actual order-value data for the store.
Why ChatGPT won Test 1
Both responses were useful, but ChatGPT was more disciplined about evidence.
Its source choices and caveats made it my preferred research draft. This is an assessment of the recorded response: the comparison does not establish that every citation or underlying factual claim was independently verified.
For a research task where the prompt explicitly required verifiable evidence and warned against guessing, that gave ChatGPT the advantage.
Score: ChatGPT 1 — Gemini 0
Test 2: Business Data Reasoning
Winner: ChatGPT
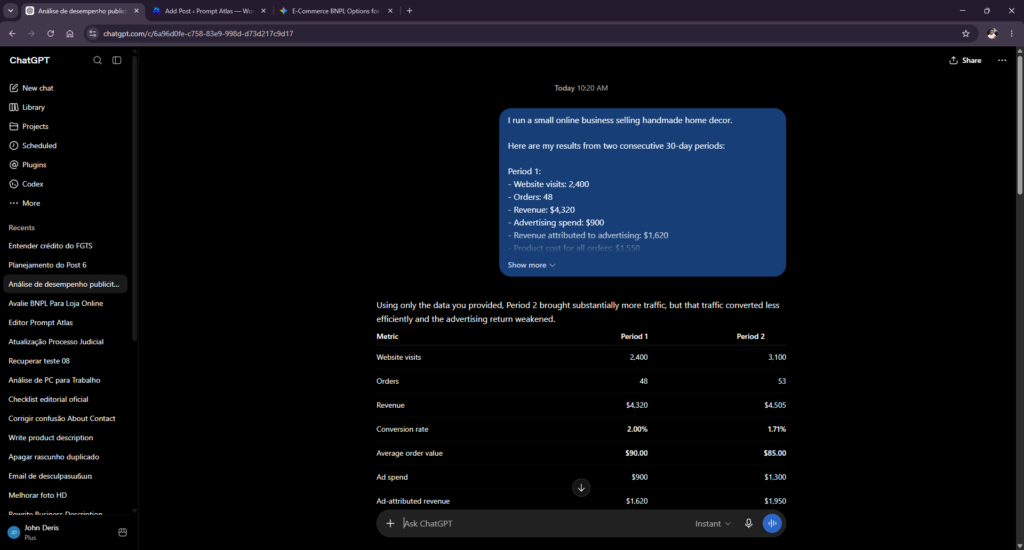
For the second test, I gave both models data from two consecutive 30-day periods.
The numbers included website visits, orders, revenue, advertising spend, advertising-attributed revenue, and product costs.
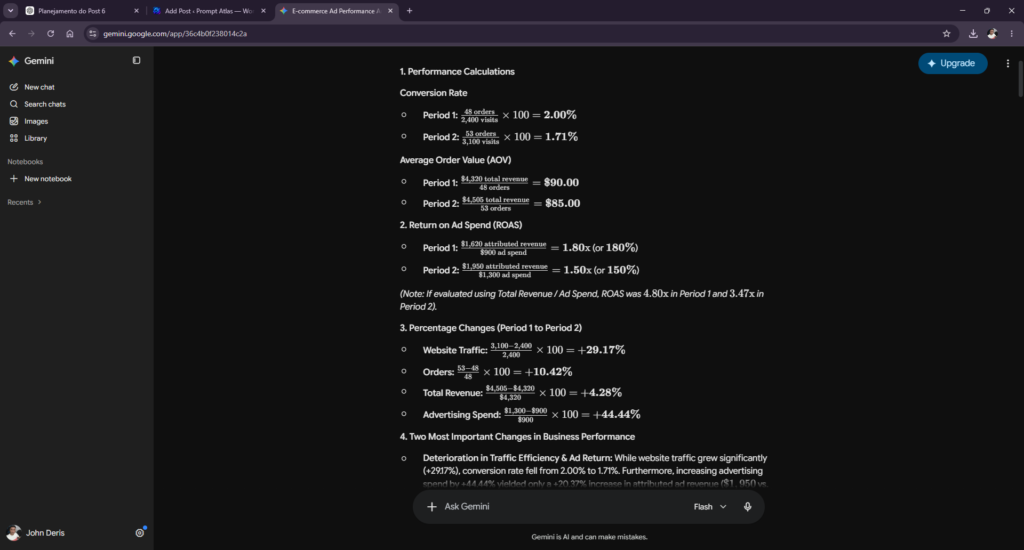
Both tools had to calculate conversion rate, average order value, ROAS, and percentage changes before deciding whether an additional $400 in advertising spend appeared justified.
This test contained an important trap: the available numbers could show changes in performance, but they weren’t enough to prove that the additional advertising caused a particular profit outcome.
Both models got the core calculations right
They calculated:
- Conversion rate: 2.00% → 1.71%
- Average order value: $90 → $85
- ROAS: 1.80x → 1.50x
- Website traffic: +29.17%
- Orders: +10.42%
- Revenue: +4.28%
- Advertising spend: +44.44%
So this wasn’t decided by basic arithmetic.
Where Gemini went too far
Gemini subtracted product costs and advertising spend from revenue for each period and used the resulting difference to support the conclusion that the additional $400 in advertising wasn’t justified.
The problem was attribution.
The supplied data didn’t establish that the extra advertising caused the overall change, and it didn’t provide the product costs specifically associated with incremental ad-driven sales.
Gemini later acknowledged some missing information, but its main conclusion was stronger than the evidence allowed.
ChatGPT handled the limitation better
ChatGPT also recognized the negative signals.
Advertising spend increased by $400 while advertising-attributed revenue increased by $330 and ROAS declined. Those simultaneous changes do not establish that the extra spend caused the revenue increase.
But it stopped short of claiming that the extra advertising had caused a specific loss.
Instead, it explained what additional information would be needed to reach a firmer conclusion.
Why ChatGPT won Test 2
Both models calculated the requested metrics correctly.
ChatGPT won because it was more careful about what those calculations could actually prove.
That distinction between identifying a worrying trend and claiming causation was the deciding factor.
Score: ChatGPT 2 — Gemini 0
Test 3: Turning Messy Business Notes Into an Action Plan
Winner: ChatGPT — by a small margin
The third test was deliberately less mathematical.
I gave both tools a collection of unorganized notes from a solo business owner.
The notes included unanswered Instagram messages, unfinished product photos, an inactive email list, questions about product dimensions, increasing website traffic, possible gift wrapping, a marketing budget, and other tasks.
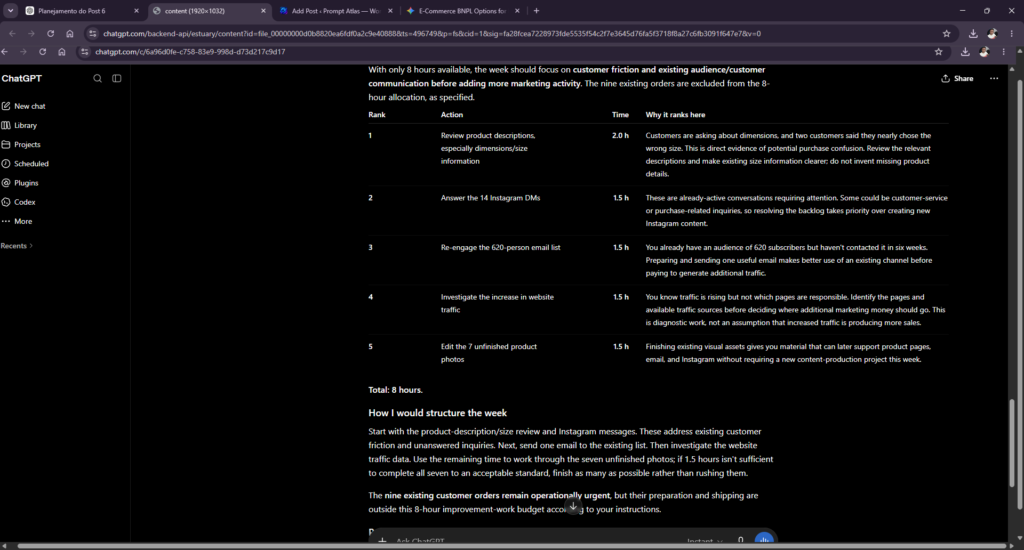
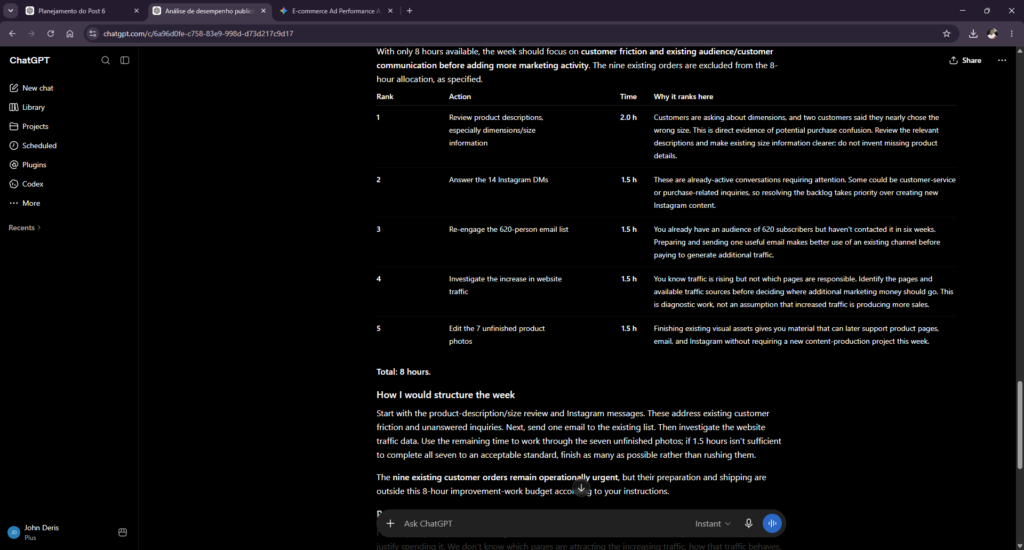
The models had eight hours to select and prioritize five business-improvement actions.
ChatGPT’s approach
ChatGPT prioritized:
- Reviewing product descriptions and size information
- Responding to unanswered Instagram messages
- Re-engaging the email list
- Investigating where increasing website traffic was coming from
- Editing unfinished product photos
It allocated exactly eight hours across those tasks.
It also correctly kept existing order fulfillment outside the eight-hour improvement budget because the prompt explicitly excluded that work.
ChatGPT didn’t treat three gift-wrapping questions as proof of broader demand, and it recommended gathering more information before spending the available $300 on advertising.
Gemini’s approach
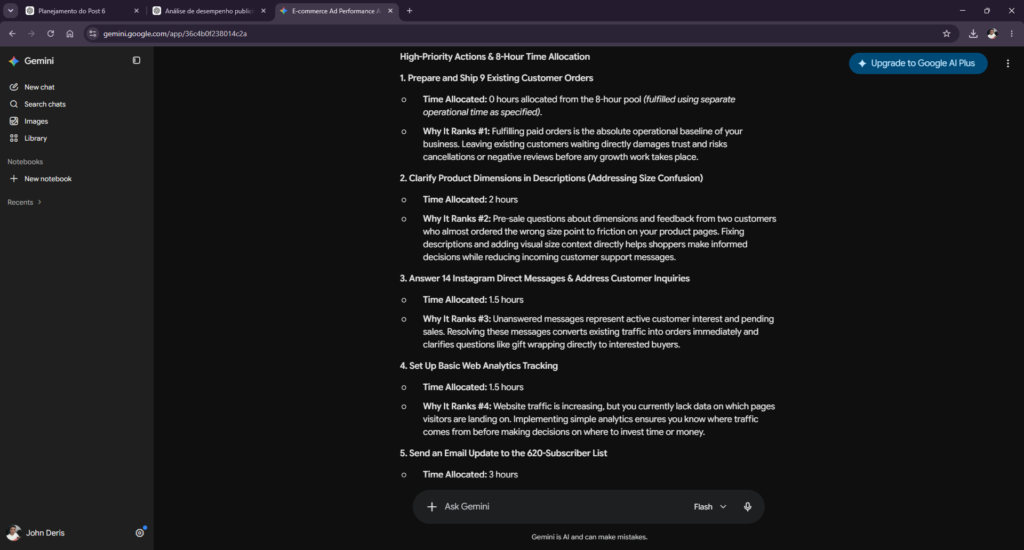
Gemini also created a practical and well-organized plan.
One of its interesting choices was prioritizing analytics while postponing the unfinished photos, which was a perfectly defensible approach.
However, it listed preparing and shipping existing orders as its number-one priority while assigning that task zero hours because the prompt excluded fulfillment from the available eight hours.
That made its five-priority structure slightly inconsistent.
It also suggested that responding to the Instagram DMs could immediately convert traffic into orders, even though the prompt didn’t tell us what those messages contained.
Why ChatGPT won Test 3
This was close.
Gemini’s plan was useful, and I could see a small-business owner following much of it.
But ChatGPT followed the time constraint more precisely and made fewer assumptions about the available information.
Score: ChatGPT 3 — Gemini 0
Test 4: Creating a 7-Day Marketing Campaign
Winner: ChatGPT — by a small margin
For Test 4, I wanted to move away from research and analysis.
Both models had to create a seven-day campaign for a new collection of personalized handmade wall decorations.
The resources were deliberately limited:
- an email list
- an online store
- a smartphone
- five total hours for campaign creation
- no paid advertising budget
They also weren’t allowed to invent materials, dimensions, prices, discounts, production times, reviews, shipping promises, or other unspecified product details.
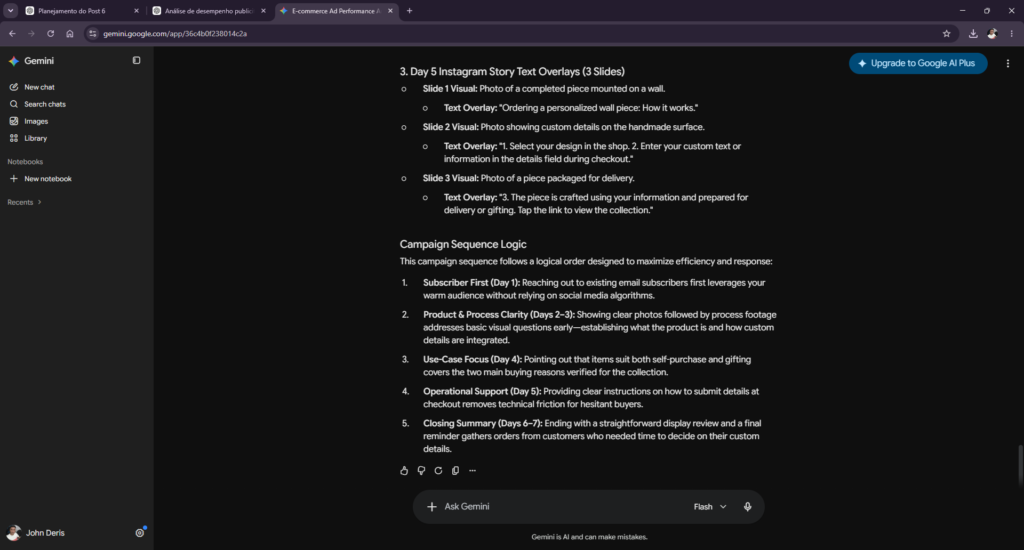
Gemini was strong creatively
Gemini created the campaign concept “Made with Your Details.”
It also provided a clear production-time breakdown and built a coherent sequence across Instagram and email.
In some respects, I preferred Gemini’s central campaign concept.
But it started adding details that weren’t in the prompt.
For example, it described a particular process for customers to select a design and enter personalization information during checkout.
The original information only said that products were personalized using customer-provided information. It didn’t explain how that information was collected.
ChatGPT stayed closer to the brief
ChatGPT used the concept “Made Personal, Made by Hand.”
Its concept may have been slightly less distinctive, but the execution was very practical.
It deliberately reused photos and videos and even included a day without a new post rather than forcing seven separate pieces of content.
That made the plan realistic for a solo owner with only five hours available.
It also stayed closer to the verified product information when writing customer-facing copy.
Why ChatGPT won Test 4
Gemini deserves credit here. Its campaign was organized and had a strong central idea.
But the prompt specifically tested whether the models could create useful marketing without filling information gaps with invented product or purchasing details.
ChatGPT handled that constraint better.
This was another narrow win.
Score: ChatGPT 4 — Gemini 0
Test 5: Handling a Difficult Customer Complaint
Result: Tie
The final test involved a customer complaint.
A customer had ordered a personalized handmade wall decoration as a gift. It arrived on time, but the customer said the personalization was wrong and claimed they had entered the correct information when ordering.
The critical detail was that the business owner hadn’t checked the original order yet.
Neither model was allowed to assume who was responsible or invent refund, replacement, return, shipping, or personalization policies.
Both models started correctly
Both ChatGPT and Gemini recognized that the first step should be checking the original order information.
They also recommended getting a photo of the received product and comparing the available evidence before deciding what happened.
Both drafted professional customer emails without immediately blaming either party.
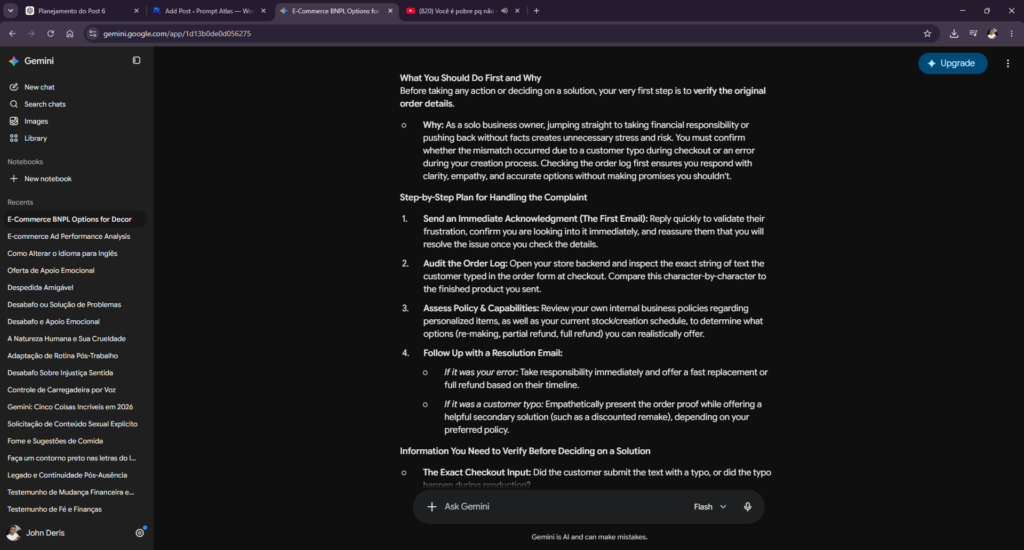
Gemini introduced possible remedies
Gemini’s response was clearly structured and practical.
When discussing possible outcomes, it introduced options such as remaking the product, issuing a full refund, offering a discount, or applying return terms.
The recorded response first instructed the owner to assess existing policies and capabilities. Its remedies were conditional options for that later decision, not statements that those store policies already existed and not immediate commitments in the first customer email.
ChatGPT kept the remedy decision open
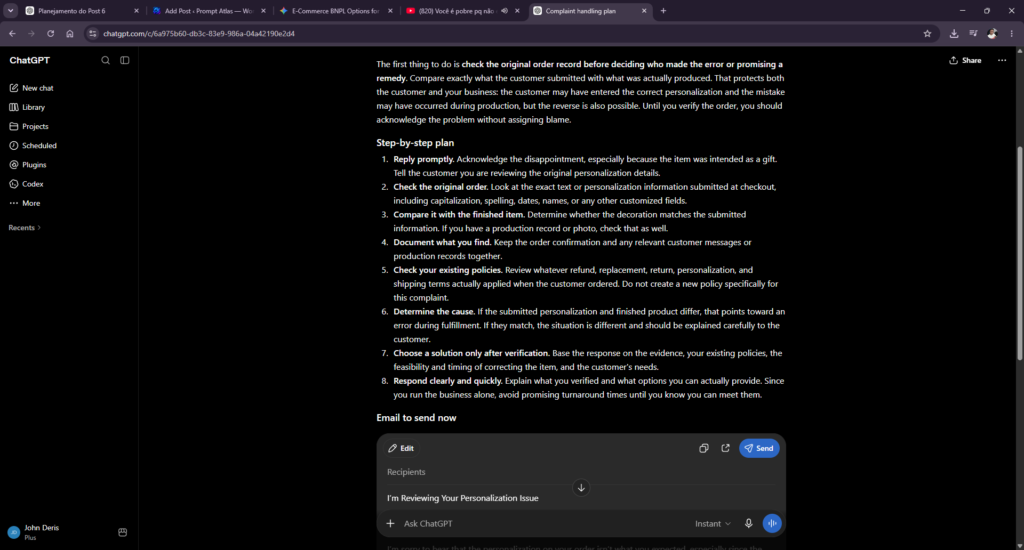
ChatGPT explicitly recognized that no refund, replacement, return, or personalization policy had been provided.
It recommended verifying the order, determining where the discrepancy occurred, checking the store’s actual policies, and only then deciding what solution could be offered.
Its customer email acknowledged the problem without admitting responsibility before the facts had been established.
Both responses could help a small-business owner handle the initial complaint.
ChatGPT’s open-ended approach is the more conservative style, but Gemini’s conditional options do not establish a policy-invention failure. Both responses begin with verification and avoid assigning responsibility in the initial reply.
Under the shared rule—do not assume responsibility or claim an unprovided policy is established—there is no sufficiently clear factual distinction to award a separate win. I therefore score this test as a tie, while retaining the difference in advice style.
Revised score: ChatGPT 4 — Gemini 0 — Ties 1
ChatGPT vs Gemini: What I Learned From the 5 Tests
The revised tally is four preferences for ChatGPT and one tie. The narrow decisions should not be read as four large performance gaps.
Gemini wasn’t consistently producing bad answers. In fact, several were useful, well structured, and easy to read.
The pattern I noticed was more specific.
ChatGPT was better at handling constraints
Across the tests, ChatGPT was generally more careful when the prompt deliberately withheld information.
When there wasn’t enough evidence to establish something, it was more likely to acknowledge the limitation rather than quietly fill the gap.
That informed my preferences in BNPL research, advertising analysis, and campaign planning. The customer complaint is different: both responses required verification, and conditional options should not be counted as established policies.
Gemini was often easier to scan
Gemini frequently organized information extremely well.
Tables, clear sections, short explanations, and practical formatting made several of its responses immediately usable.
Its marketing campaign concept was also one of its strongest moments in the comparison.
Small assumptions made a big difference
This became the most important lesson from the entire test.
Most of Gemini’s questionable assumptions were plausible.
That’s precisely why they matter.
A business owner could easily read a plausible statement and treat it as something established by the available information.
The best AI response isn’t always the one that provides the most detail. Sometimes it’s the one that knows which details it doesn’t actually know.
Which Is Better for Small Business: ChatGPT or Gemini?
Based on these five tests, ChatGPT was the better performer for my small-business scenarios.
It won the research and data-analysis tests because it handled evidence and uncertainty more carefully.
It narrowly won the planning and marketing tests because it followed detailed constraints more consistently.
The customer-service test is a tie: both responses called for verification, and Gemini’s conditional remedies are not equivalent to invented store policies.
Gemini still showed strengths in organization, presentation, and practical idea generation.
So I wouldn’t interpret this test as evidence that Gemini is a poor business tool — or that ChatGPT will win every task.
The result is narrower than that:
For the same five recorded small-business tasks, I prefer ChatGPT in four and find no clear winner in the customer-complaint task.
Final Verdict: Four Preferences and One Tie
My final result for this ChatGPT vs Gemini for small business comparison is:
ChatGPT: 4 preferred responses
Gemini: 0 sole wins; 1 shared tie
The planning and campaign preferences remain narrow. The revised customer-service tie corrects the earlier treatment of conditional suggestions; no new model runs were conducted.
Still, a consistent pattern emerged.
ChatGPT was better at recognizing when the information provided wasn’t enough to support a conclusion. It also followed restrictions more carefully and introduced fewer unsupported business assumptions.
Gemini’s strengths were different. Its answers were often well organized, visually clear, and practical.
For the kinds of small-business tasks I tested here, though, I would choose ChatGPT.
Want to see how ChatGPT performed against another major AI assistant? Read my ChatGPT vs Claude for small business comparison, based on five real-world tests.
The reason isn’t that it always wrote more or generated more ideas.
ChatGPT more often gave me the starting point I preferred under these constraints. That conclusion is limited to these outputs and does not imply that every suggested option in Gemini was an invented fact.
If you’re comparing more options, see my guide to the best AI tools for small business, where I test and evaluate tools for practical business tasks.
Frequently Asked Questions
Were ChatGPT and Gemini tested on the same business tasks?
Yes. Using the same scenarios makes it easier to see how each tool handles the same brief, constraints, and expected output.
Which tool had the stronger overall result in this comparison?
ChatGPT had the stronger overall result in this test set, while Gemini remained useful for structured brainstorming and alternative drafts. That result is not a guarantee for every workflow.
Should a business switch tools based only on this article?
No. Re-run the most important task with your own data, check privacy and pricing, and measure whether the tool actually saves time.
What is the most important lesson from the tests?
A reliable workflow depends on clear instructions and human checking. A fluent answer is not automatically a correct or business-ready answer.
Leave a Reply